RESEARCH · IDEAS · THINGS I BUILD

Hello, I'm
Qing He 贺青若.

I’m a Research Scientist
working on multimodal and conversational AI.

I’m a Research Scientist focused on applied AI, with in-depth experience in modeling such as multimodal LLM training, diffusion models, and representation learning, etc. What I enjoy most is applying my research expertise to originate compelling product ideas and drive them from concept to launch. I take a hands-on role throughout that journey, testing hypotheses, iterating on model improvements and product experiences, and refining the system until the research becomes a solid product. At Meta, I’ve combined this research depth with extensive experience building models for real products, from conversational voice and expressive avatars to wearable devices and creator tools. I work across the full stack, connecting model quality with systems engineering to create engaging user experiences. I also have extensive hands-on experience with model optimization and deployment spanning model architecture/inference co-design and inference optimization across GPUs, CPUs, and edge devices, enabling applications that deliver both high-quality experiences and the low latency and efficiency required for real-time interaction.

I've been at Meta (previously Facebook) since April 2017. I earned my Ph.D. and M.S. in Electrical Engineering and Computer Science from MIT, and my B.S. in Electrical Engineering from the University of Waterloo. Before university, I attended Unionville High School in Markham, Canada.

CURRENT INTERESTS
Conversational AISpeech generationEfficient inference
SELECTED WORK

Projects

From research to real experiences.

Building natural, expressive voice experiences—and the systems that make them possible.

VOICE & INTERACTION

Expressive conversational AI

I drove improvements in speech naturalness and expressiveness, helping Muse’s avatars speak with a more lifelike, engaging voice. I helped develop full-duplex voice technology for Meta AI, shaping a more fluid, spontaneous experience that feels closer to human conversation.
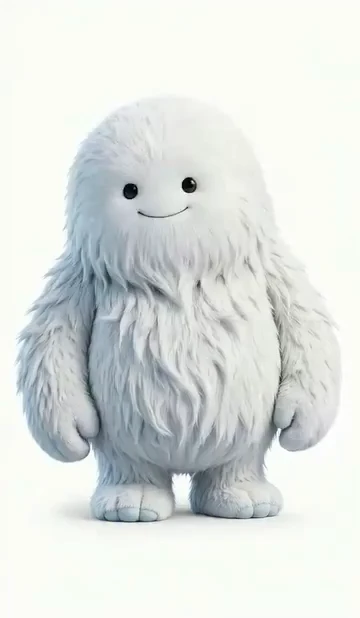
Muse avatar character from Meta’s realtime avatar demonstration.

Muse Avatar

Muse Realtime Avatar brings characters into live conversation with expressive speech synchronized to facial and full-body movement. A shared speech-token stream connects voice and animation, helping each character’s delivery and visual performance feel coherent.

Meet Muse Avatar
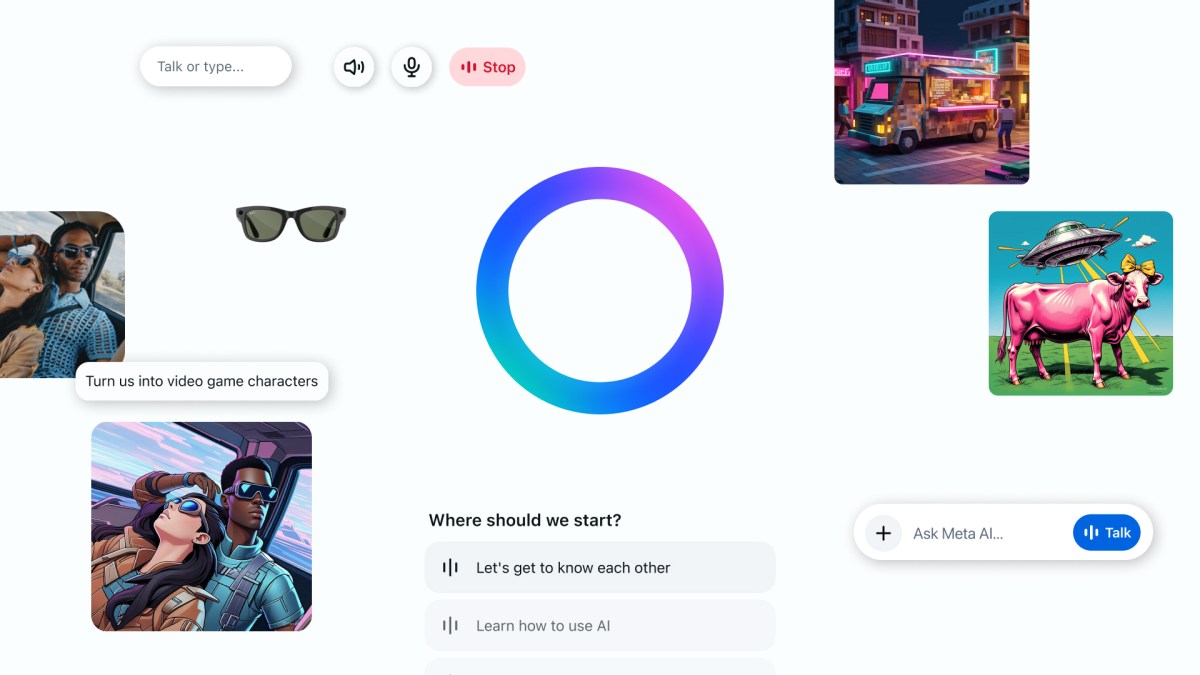
Meta AI app imagery featuring its voice interface and gradient AI ring.

Meta AI Full-duplex Voice

The Meta AI app introduced a full-duplex demo trained on conversational dialogue. It generates voice directly instead of reading a written response aloud, exploring a more natural rhythm for spoken interaction with an AI assistant.

Read the announcement
WEARABLES & DEVICES

Voice for Meta Hardware

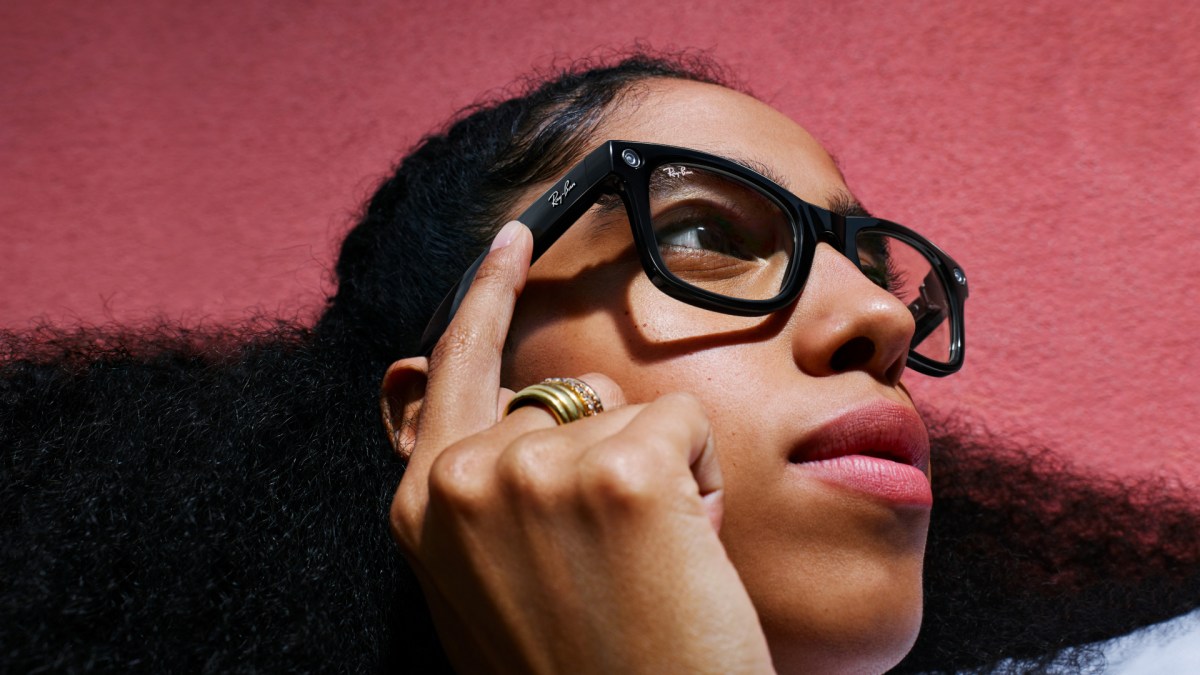
I led development of text-to-speech voices for Meta’s hardware devices, spanning server and on-device deployment. The work brought together multilingual support and a broad range of voice capabilities across Ray-Ban Meta glasses, Oculus, and Portal.

Ray-Ban Meta smart glasses worn during a hands-free interaction.

Ray-Ban Meta glasses

Ray-Ban Meta glasses put a conversational assistant into everyday eyewear. “Hey Meta” lets people ask questions and control features by voice, with spoken responses through open-ear speakers that keep the experience hands-free while they stay engaged with the world around them.

Read the announcement
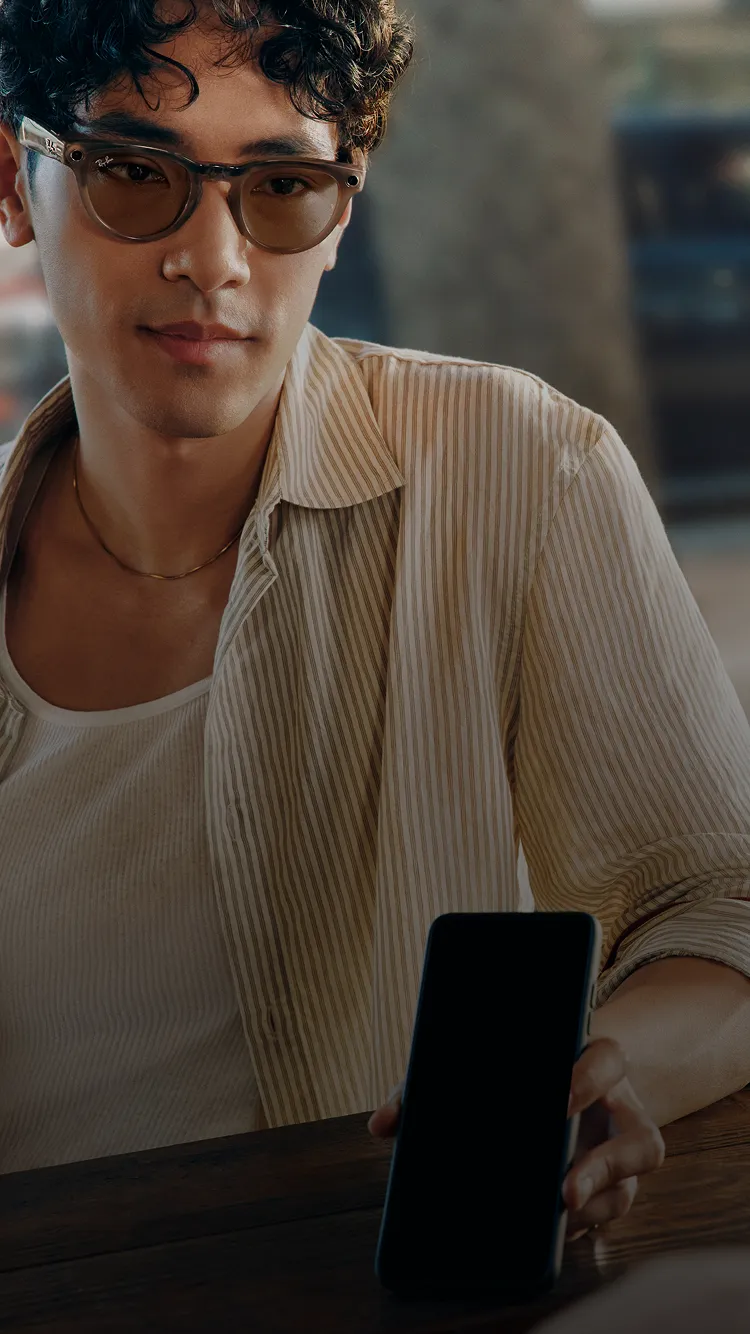
A person wearing Ray-Ban Meta glasses with a phone during a live translation experience.

Live translation

Live translation turns speech in another language into translated audio played through the glasses’ speakers, with a transcript in the Meta AI app. It connects speech understanding, translation, and speech generation to help people follow conversations without repeatedly looking down at a phone.

Explore live translation
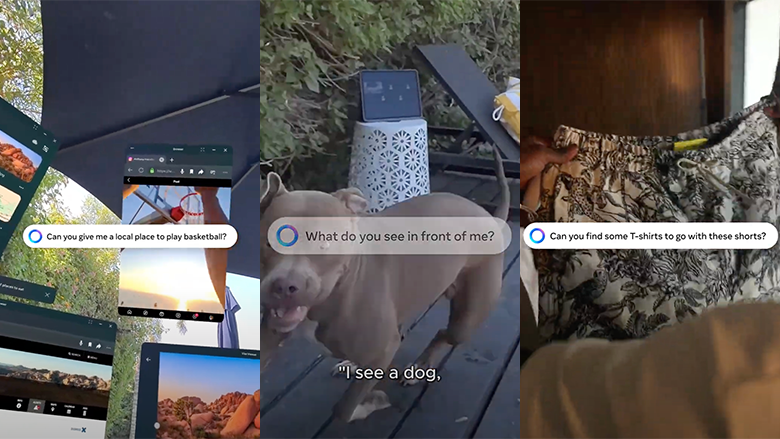
Examples of spoken questions and contextual answers in Meta Quest mixed reality.

Meta AI on Quest

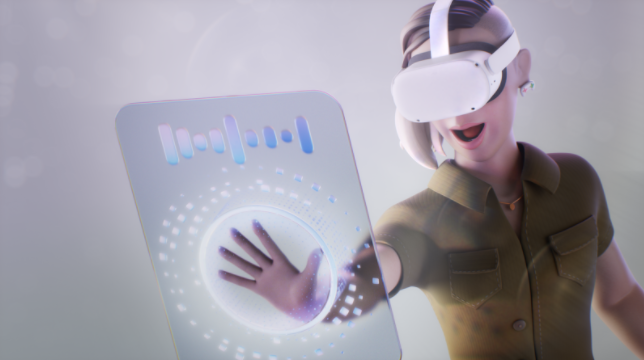
Meta AI brings voice-based assistance into VR and mixed reality. People can control supported headset features, ask questions, and receive spoken answers while staying in-headset. With Passthrough, they can also ask about objects in their physical surroundings.

Explore Meta AI on Quest
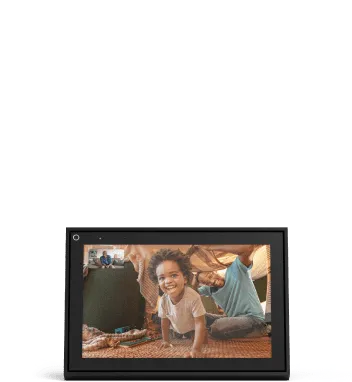
Meta Portal display showing a family video call.

Portal

Portal brought hands-free video calling and voice assistance to the home. “Hey Portal” let people start calls and access spoken briefings, while neural text-to-speech powered natural assistant responses—making everyday interactions possible through speech instead of tapping through menus.

Explore Portal
CREATORS & DEVELOPERS

AI for Creative Tools

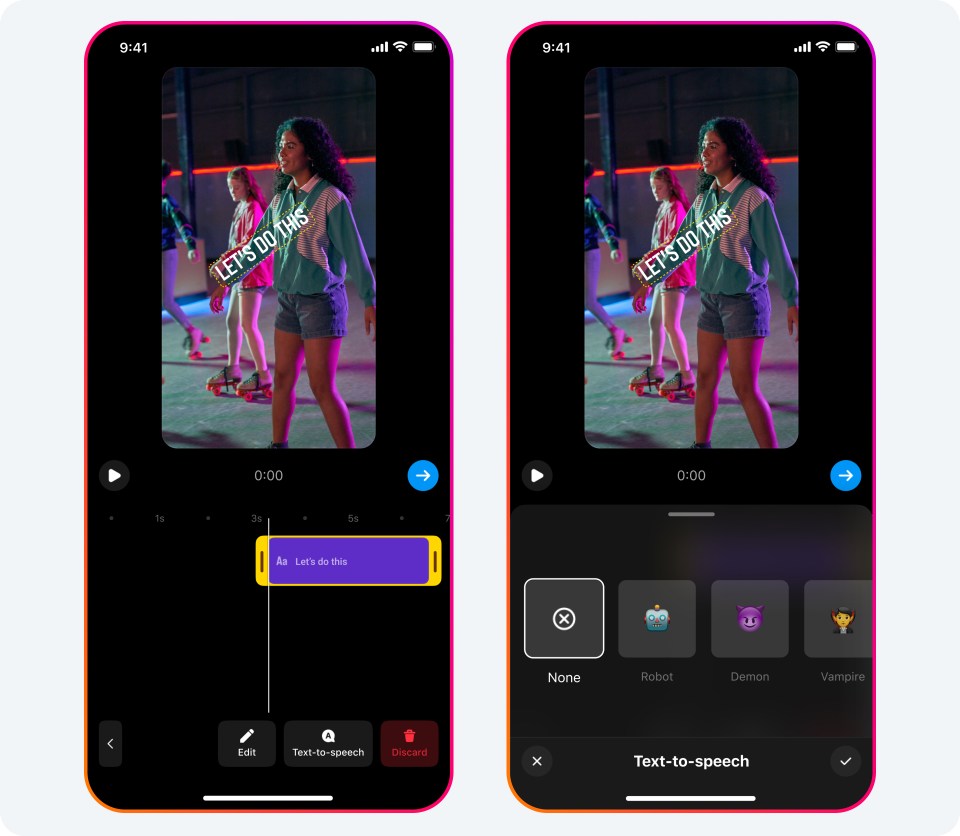
I partnered with product teams to bring AI capabilities into creative tools, supporting experiences across Instagram, AI Studio, and the Voice SDK.

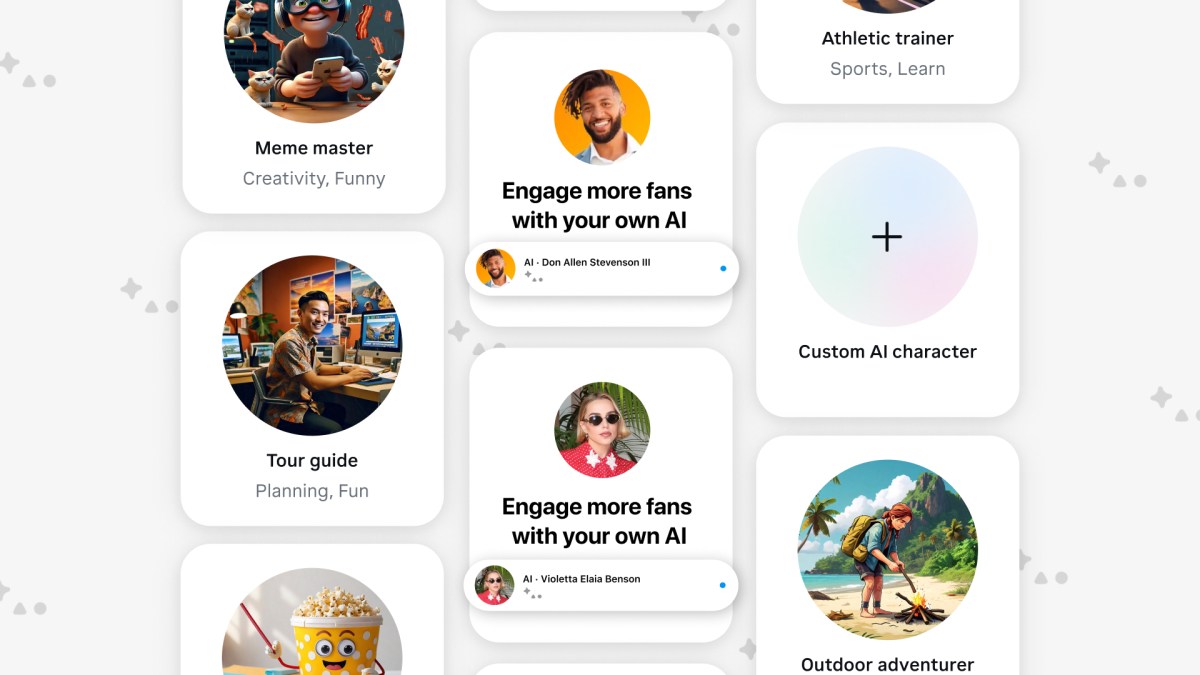
AI Studio launch artwork showing AI characters and creator profiles.

AI Studio

AI Studio introduced tools for building custom AI characters and creator personas. By defining personality, tone, and conversational behavior, creators could shape interactions that reflected their own style and extend their presence across Meta’s messaging experiences.

Read the AI Studio announcement
Official Voice SDK illustration showing a VR character and a voice interaction panel.

Voice SDK

Voice SDK brings together speech recognition, language understanding, and text-to-speech for developers. In VR, people can navigate with spoken commands, ask for help, and hear characters respond—making voice an interactive part of an app or game.

Explore Voice SDK
MODELS TO PRODUCTION

Efficient AI Inference

I worked extensively on inference optimization across server GPUs and mobile edge devices, making high-quality models practical within the compute and latency constraints of real products.

Conceptual illustration of a processor and mobile device linked by an audio waveform.

Real-time text-to-speech on CPUs

A neural text-to-speech system combined model and system optimization to deliver natural speech in real time on CPU servers. Deployed in Portal, the system demonstrated how efficient synthesis could support spoken assistants and other speech applications without specialized serving hardware.

Read the technical article
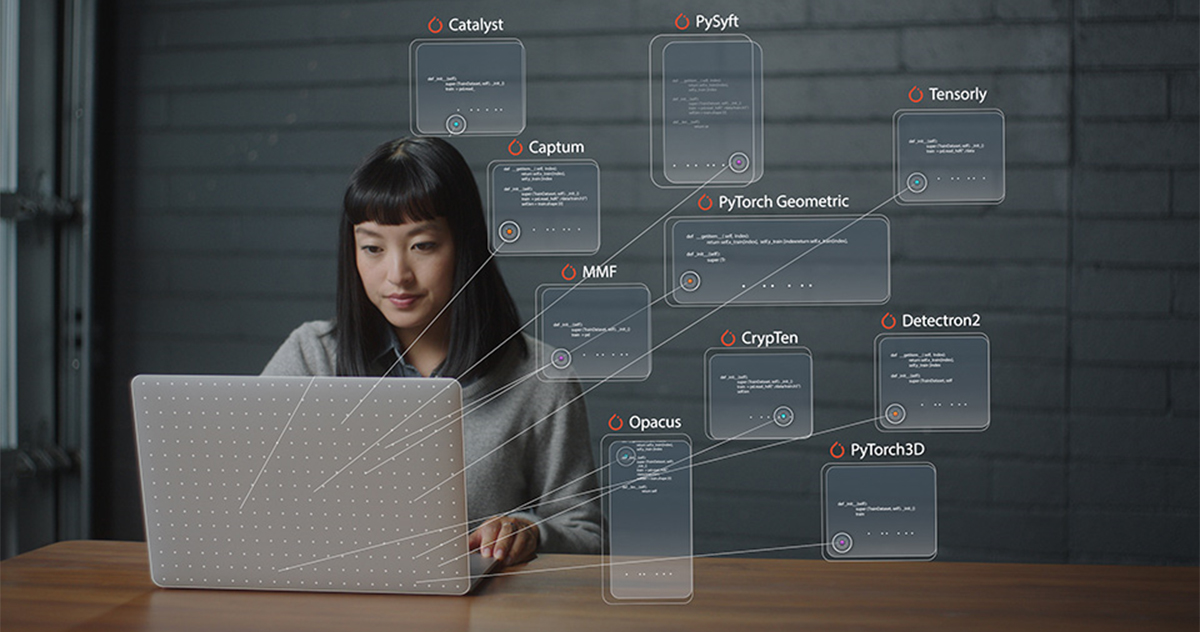
Official PyTorch article artwork showing its software ecosystem and a developer at a laptop.

PyTorch for production speech systems

PyTorch supported the TTS team’s path from model experimentation to deployment through optimized operators, TorchScript, and a lightweight mobile runtime. These tools helped deliver speech inference with a low compute and memory footprint across server and smaller-device environments.

Explore the production stack

Product imagery: Meta · Inference illustration: AI-generated

WRITING & RESEARCH

Recent publications

2024–2026

Recent work on speech, language, and the models that connect them. Full list on Google Scholar

2026 SPOKEN REASONING

Spoken Language Models that Think Aloud

SLT 2026 · Accepted

An asynchronous speech framework lets a model share short progress updates while it continues reasoning. Coordinating a reasoning stream with a lightweight speaking stream reduces audible silence while preserving answer accuracy in spoken reasoning and question answering.

Authors

Junyi Ao, Kainan Peng, Mingbo Ma, Shun Zhang, Zhenyu Tang, Xutai Ma, Xiang Li, Yinghao Li, Yuancheng Wang, Zhizheng Wu, Haizhou Li, Qing He, Xubo Liu

2026 SPEECH EVALUATION

GSRM: Generative Speech Reward Model for Speech RLHF

arXiv · Preprint

A speech reward model evaluates naturalness through acoustic features and explicit reasoning, making its judgments easier to interpret. Trained with expert feedback, it aligns closely with human ratings and can guide reinforcement learning toward more natural speech.

Authors

Maohao Shen, Tejas Jayashankar, Osama Hanna, Naoyuki Kanda, Yancheng Wang, Kateřina Žmolíková, Ruiming Xie, Niko Moritz, Anfeng Xu, Yashesh Gaur, Gregory Wornell, Qing He, Jilong Wu

2026 SPEECH REPRESENTATIONS

Scaling Speech Tokenizers with Diffusion Autoencoders

ICLR 2026

SiTok combines semantic representation learning with diffusion-based audio reconstruction. Scaling the tokenizer improves speech understanding, reconstruction, and generation while operating at just 12.5 tokens per second and 200 bits per second.

Authors

Yuancheng Wang, Zhenyu Tang, Yun Wang, Arthur Hinsvark, Yingru Liu, Yinghao Li, Kainan Peng, Junyi Ao, Mingbo Ma, Mike Seltzer, Qing He, Xubo Liu

2026 SPEECH & EMOTION

VowelPrompt: Hearing Speech Emotions from Text via Vowel-level Prosodic Augmentation

ICLR 2026

VowelPrompt translates vowel-level pitch, energy, and duration into natural-language cues. These cues help language models recognize emotion using both the words and how they are spoken, with explanations grounded in prosody and context.

Authors

Yancheng Wang, Osama Hanna, Ruiming Xie, Xianfeng Rui, Maohao Shen, Xuedong Zhang, Christian Fuegen, Jilong Wu, Debjyoti Paul, Arthur Guo, Zhihong Lei, Ozlem Kalinli, Qing He, Yingzhen Yang

2025 VOICE CONVERSION

SemAlignVC: Enhancing Zero-shot Timbre Conversion Using Semantic Alignment

Speech Synthesis Workshop 2025

SemAlignVC aligns text and audio representations to separate linguistic content from speaker identity. This reduces leakage of the original speaker’s timbre during zero-shot voice conversion, improving target-voice similarity, intelligibility, and naturalness.

Authors

Shivam Mehta, Yingru Liu, Zhenyu Tang, Kainan Peng, Vimal Manohar, Shun Zhang, Mike Seltzer, Qing He, Mingbo Ma

2025 SPEECH GENERATION

Get Large Language Models Ready to Speak: A Late-fusion Approach for Speech Generation

ICASSP 2025

TTS-Llama adapts a language model for speech synthesis. MoLE-Llama then combines text and speech through parameter-efficient late fusion and a mixture-of-experts design, supporting spoken responses while retaining text question-answering capabilities.

Authors

Maohao Shen, Shun Zhang, Jilong Wu, Zhiping Xiu, Ehab AlBadawy, Yiting Lu, Mike Seltzer, Qing He

2024 FOUNDATION MODELS

The Llama 3 Herd of Models

arXiv · Technical report

A technical report on the Llama 3 family of multilingual models for coding, reasoning, and tool use. It describes training and evaluation at scale, including a 405-billion-parameter model, and explores adding image, video, and speech capabilities.

Authors

Aaron Grattafiori et al. (including Qing He; see the paper for the complete author list)

2024 TEXT-TO-SPEECH

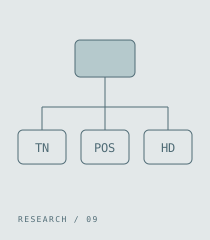
Multi-Task Learning for Front-End Text Processing in TTS

ICASSP 2024

A shared model handles text normalization, part-of-speech tagging, and ambiguous-word pronunciation together. Combining shared representations with task-specific heads improves overall performance, while a balanced homograph dataset strengthens pronunciation disambiguation.

Authors

Wonjune Kang, Yun Wang, Shun Zhang, Arthur Hinsvark, Qing He

Research papers and preprints from the past three years · Updated October 2026

Let’s connect.

For research conversations, collaborations,
or just to say hello.